Scale Your Data Annotation Without Sacrificing Quality
Build reliable AI training datasets with trained, in-house annotators and dedicated QA. BUNCH manages the people, process and quality control so your ML team can focus on building better models.
Keep your platforms protected with reliable 24/7 coverage
Annotation Accuracy
High-quality labels for reliable AI training
Faster AI Deployment
Scalable annotation that speeds up development
Data Points Annotated
Powering AI with expertly labeled datasets
Unmatched Accuracy Standards for AI and ML
We understand that even a few errors in your training data can compromise the integrity of entire datasets. Over the past years, we have diligently refined our QA audit processes, trained our labelers, and determined the ideal team structure balance among Labelers, Team Leads, Quality Assurance Specialists, and Project Managers to deliver the highest possible data quality without sacrificing productivity.
We continuously enhance our QA Scorecards and retrain our annotators and linguists based on guidelines through iterative improvements, adding what we learned from client-specific edge cases in each iteration. We carefully select the most suitable labelers for each training data media type. BUNCH has a seasoned team of high-touch project managers who have had extensive exposure to ML models, and our entire organization is guided by a single, shared mantra: Data Quality.
Trusted by


High-Precision Data Labeling for AI
Supercharge your ML pipeline with expert annotators, 24/7 operations and tailored workflows built for your data. A managed data annotation team that takes the operational burden off your ML team.
Annotation Experts Since 2018
We’ve been labeling and annotating data since 2018, building deep expertise across computer vision, NLP, and multimodal datasets
Every Team Has a Quality Structure
Team Leads, Workforce Managers, and QA specialists work together to keep your annotation team organized, productive, and consistent.
Consistency As You Scale
We don’t just follow guidelines. We own them, refine them, and continuously add edge cases to improve consistency as your dataset evolves.
95% Accuracy
Proven quality and speed you can measure, backed by rigorous QA processes and continuous checks to keep your data accurate and consistent.
Custom Workflows
We build the process around your data, not the other way around. Review steps, escalation paths and QA gates all shaped to how your team works.
We handle Data Ops Projects from Thousands to Billions of Datapoints
We assign compact teams consisting of a few annotators to handle smaller projects involving several thousand images or audio files and deploy teams of dozens of annotators for large-scale projects spanning several months. To ensure rapid response and scalability, we maintain a large pool of experienced annotators who can be mobilized within days, reaching hundreds of labelers when necessary. Projects can be structured based on an agreed output, such as millions of labeled images or hundreds of hours of transcribed speech audio in various languages.
For many clients in the AI space, we arrange full-time teams with a specified number of FTEs (Full-Time Employees) to address recurring data needs, which is the most cost-efficient approach for generating substantial volumes of training data for long-term ML models requiring ongoing data input. Occasionally, we maintain a fixed team to produce a specific amount of data while employing a flexible, part-time team to manage seasonal surges.
Pricing is determined based on output, such as the number of images labeled, audio hours transcribed, polygons or bounding boxes annotated, and text clips categorized. Alternatively, it can be based on the number of Full-Time Employees (FTEs) allocated to the project.
DATA ANNOTATION
TECHNIQUES WE MASTER
Image Annotation
Categorize and label objects within images
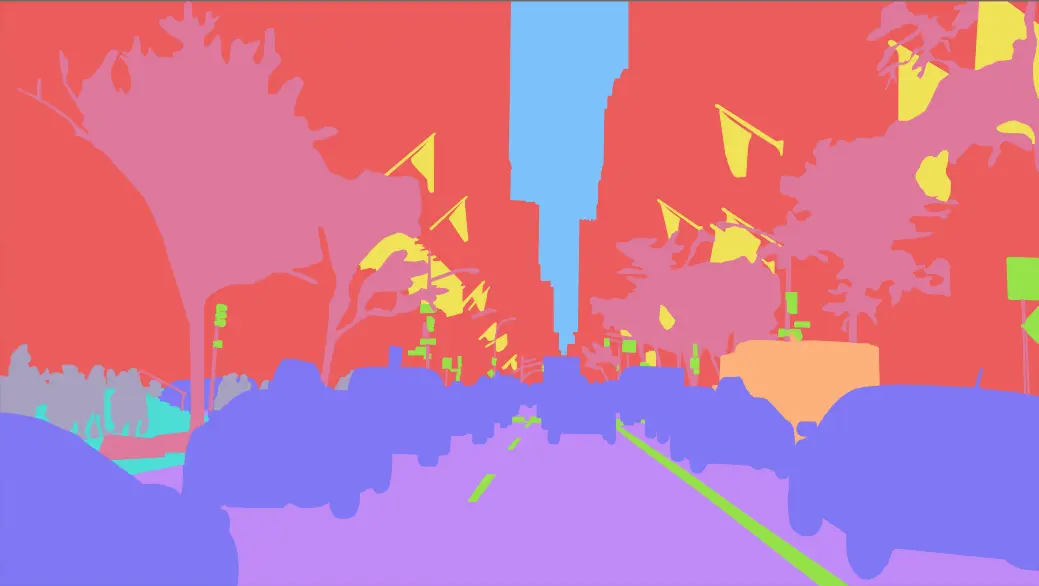
Semantic Image Segmentation
Annotation of segments in images for machine learning
Audio Transcription
Transcribe natural spoken language into text for data training
Text Annotation
Add structural and linguistic metadata to text
Video Annotation
Tag and track objects in video frames
Sentiment Analysis
Extract sentiment and insights from textual data
Lidar Annotation Outsourcing
Annotate Lidar spacial datasets for autonomous vehicles
Keypoint Annotation
Train your datasets with precise keypoints with unparalleled accuracy
Bounding Box
Annotate boxes to locate and identify objects in training images
Drive business growth with scalable AI solutions
The best AI is built on accurate data, expert validation, and continuous human feedback. From data annotation to model evaluation and fine-tuning, we help you develop reliable AI solutions that scale with confidence.
Getting Started with Data Labeling
Start your AI or ML project with a trained data labeling team. BUNCH provides human-powered annotation for computer vision, NLP and other AI applications across industries.
We begin with a calibration test using a sample of your data to understand your labeling guidelines, identify improvements, measure task times, and determine the right team structure for your project.
Once calibrated, we build a scalable team around your workflow, with 24/7 coverage available for time-sensitive projects.
Choose Plan
Choose your labeling package and scope.
Set Rules
Finalize annotation rules and quality standards.
Run Pilot
Review sample output and refine instructions.
Integrate Systems
Connect secure data workflows to your systems.
Launch Production
Receive continuous streams of high-quality data.
Train your ML Models with Proven and Tested Labeling Techniques and Industry Experts
Our Data Ops Team boasts industry experience in providing training data for AI and ML applications, with a particular focus on computer vision. This includes data tagging for various domains such as self-driving vehicles, healthcare, robotics, precision agriculture, geospatial intelligence, education, energy, and medical AI. We collaborate with numerous R&D departments at top universities in the US, UK, Singapore, Canada, and China. We support Natural Language Processing AI programs for global organizations across various industries, including retail, eCommerce, manufacturing, and private Deep Learning initiatives.
Our processes and technology have enabled our clients to maintain a consistent flow of structured training data that powers algorithms by utilizing human inputs and intelligence. We allocate teams to operate 24/7 when a project's quick turnaround time is vital.
Before onboarding our clients, we typically perform a calibration test, in which we run a labeling trial using a representative data sample from the entire dataset. This helps us understand the guidelines (and suggest improvements for increased efficiency), determine the average handle time (AHT) for each task, and design the most optimized team for scaling the task effectively.
PROUD OF OUR TEAM
Meet our specialists team. Most of our employees are young top-talent in the Philippines and Indonesia, international tech labor hubs that nurture an ambitious, non-entitled youth deeply motivated by two core values rooted in their culture: career and family.
Our vision is to create a rich fabric of opportunities to grow our team’s careers and to sustainably support their families. This is essential in fast-developing societies where the aspirations of most families rest on the talent of the young and their careers in the new tech economy.
Talk to a Bunch Expert Today


Tell us what you’re labeling, how much data you have and what quality you need.
Frequently Asked Questions
Explore answers for the most common questions from our trusted partners and clients
What Is Data Annotation in Machine Learning?
Data annotation in machine learning is the process of labeling raw data so that an AI model can learn from examples. It adds structure to text, images, audio and video by marking what each item means according to a predefined set of rules.
How Do Quality Audits Work in Data Annotation?
Quality audits involve a dedicated QA team reviewing a sample of completed annotation work to check it against the project's guidelines.
When Should a Company Outsource Data Annotation?
A company should outsource data annotation when data labelling volume becomes too large, too continuous or too quality-sensitive to manage comfortably with an in-house team. This usually happens when dataset volumes increase, model timelines tighten, or internal product and machine learning (ML) teams start spending too much time coordinating labellers instead of building the model itself.
What Types of Data Can BUNCH Annotate?
At BUNCH, our expert teams specialize in annotating text, images, video and audio, the core data types used to train language models, computer vision systems, speech models and multimodal AI.

A Brutal Disruption in Image Annotation Services in 2025
AI data labeling just got disrupted. Generalist models are out, and expert-driven, specialized data is in. Here’s how the landscape is evolving faster than anyone expected.

Our Managed Services Model
Learn how our managed services are designed to shoulder all operational responsibilities, offering clients streamlined, process-based operations under a flat monthly fee, allowing them to focus on growth.

Scalable Data Labeling Solutions: Growing Teams Without Compromising Quality
Learn how to scale data labeling for ML without sacrificing quality through double-pass annotation, AI integration, dedicated teams, continuous training, and strong project management.

How We Are Obsessed About Data Quality and Why
We understand the importance of reliable data quality for training datasets and precision in moderating user-generated content. Learn how we apply rigorous QA in all our processes.