8 Managed Services Examples for Tech Operations
The best managed services examples are bounded workflows with clear ownership, measurable service levels, quality review and escalation paths. The managed services market was valued at USD 401.2 billion in 2025 and is projected to reach USD 847.4 billion by 2033, but the useful lesson is simpler. Outsourcing works when a provider owns an operating system, not when a company only adds external hands.
In practice, a provider can own annotation queues, moderation decisions within defined policy limits, support tickets, identity checks or model evaluations. Your team should keep product direction, policy ownership, regulatory accountability and high-risk decisions. At BUNCH, we've been building custom outsourced teams for fast-growing tech companies, working from our offices in Metro Manila and Cavite since 2017. Most of our clients are in the US and Europe. We're not a staffing marketplace or a labeling platform. What we do is run managed, human-in-the-loop operations.
The examples below focus on what makes a service work: scope, handoffs, service levels, quality controls, internal responsibilities and trade-offs.
1. Data Labeling and Annotation for Machine Learning
ML teams rarely fail because they lack a labeling tool. They fail because people interpret edge cases differently.
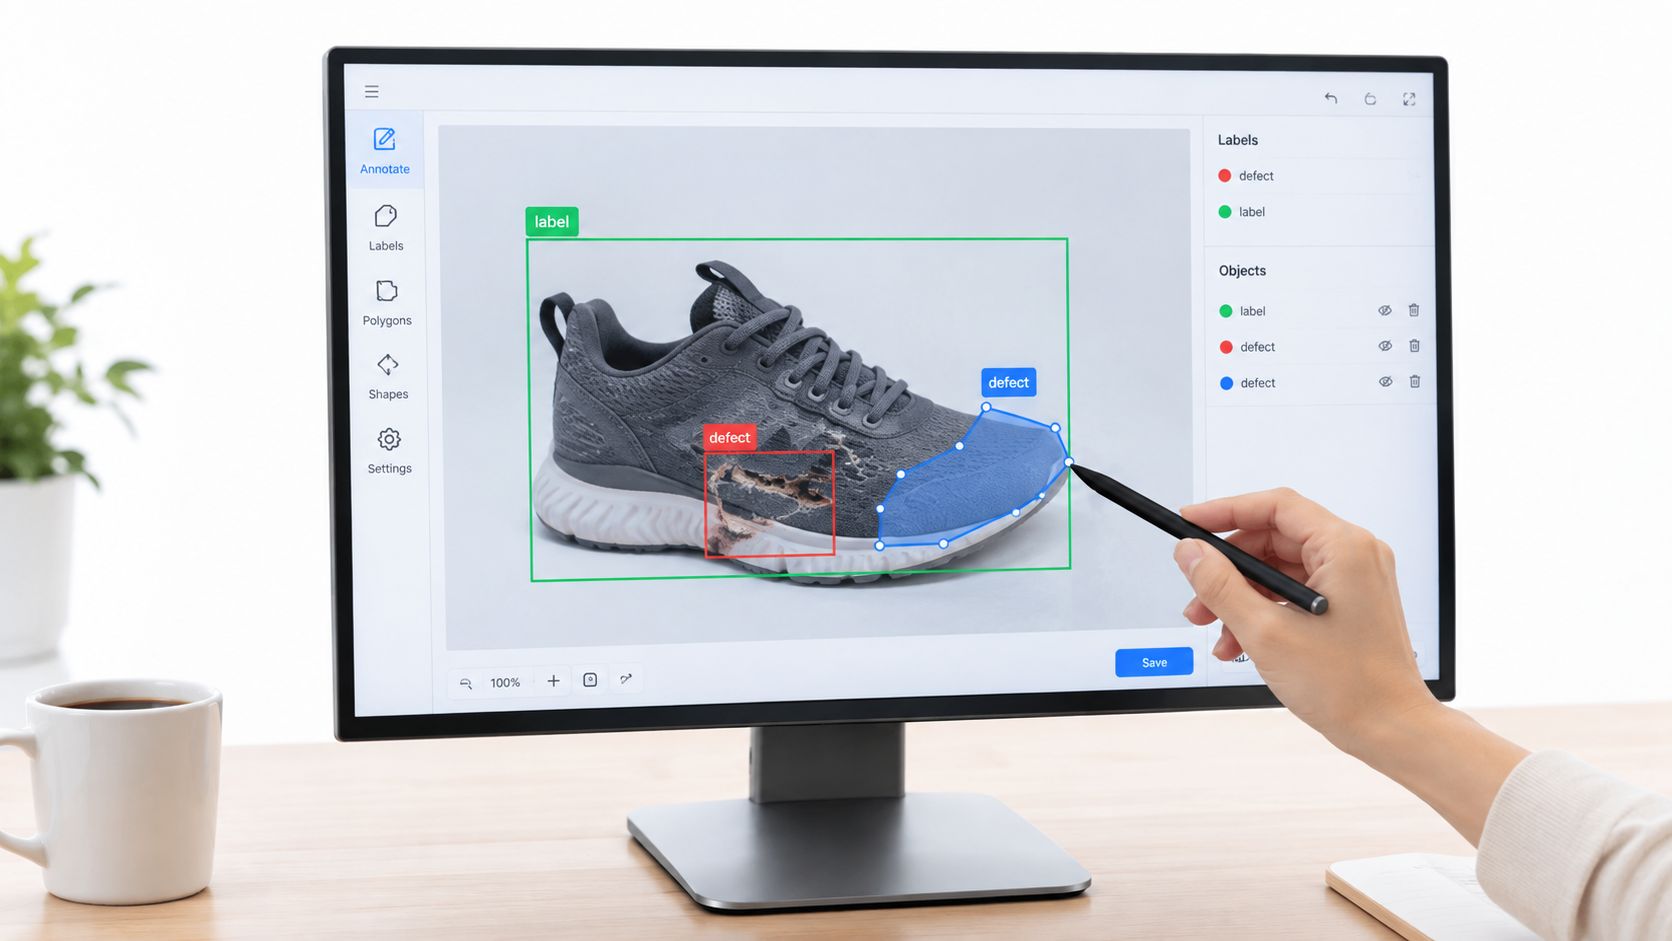
A managed annotation team turns raw images, video, text, audio or LiDAR into structured training data. That can include bounding boxes, segmentation masks, keypoints, intent labels, toxicity labels or sequence classifications. The provider owns staffing, queue management and first-pass production. Your ML team owns the taxonomy, acceptance criteria and adjudication of disputed cases.
A computer vision team might send damaged shoe images to an annotation queue. An autonomous vehicle team may need pedestrians and vehicles marked across consecutive frames. An LLM team may require text labeled for intent, toxicity or factual accuracy before fine-tuning.
A written guide matters more than a kickoff call. Put 10 to 15 real examples and edge cases in the guide, then begin with 500 to 1,000 items before releasing the full dataset. A double-pass review, where a second annotator checks the first, catches ambiguity early.
Practical rule: Treat disagreement as data. A disagreement queue often reveals a weak taxonomy, not a careless annotator.
Expect a 2 to 3 week ramp as the team learns your domain. That is cheaper than introducing inconsistent labels into production. Require annotation tools to retain annotator ID, timestamp and guideline version so quality trends stay traceable.
This is work we do every day. We run data labeling and annotation services across image, video, text, audio and LiDAR workflows. Outsourcing is a poor fit when labeling rules change daily or your internal experts cannot review disputed cases.
2. Content Moderation and Trust and Safety Operations
Moderation becomes an operating problem when reports arrive faster than product or policy teams can review them.
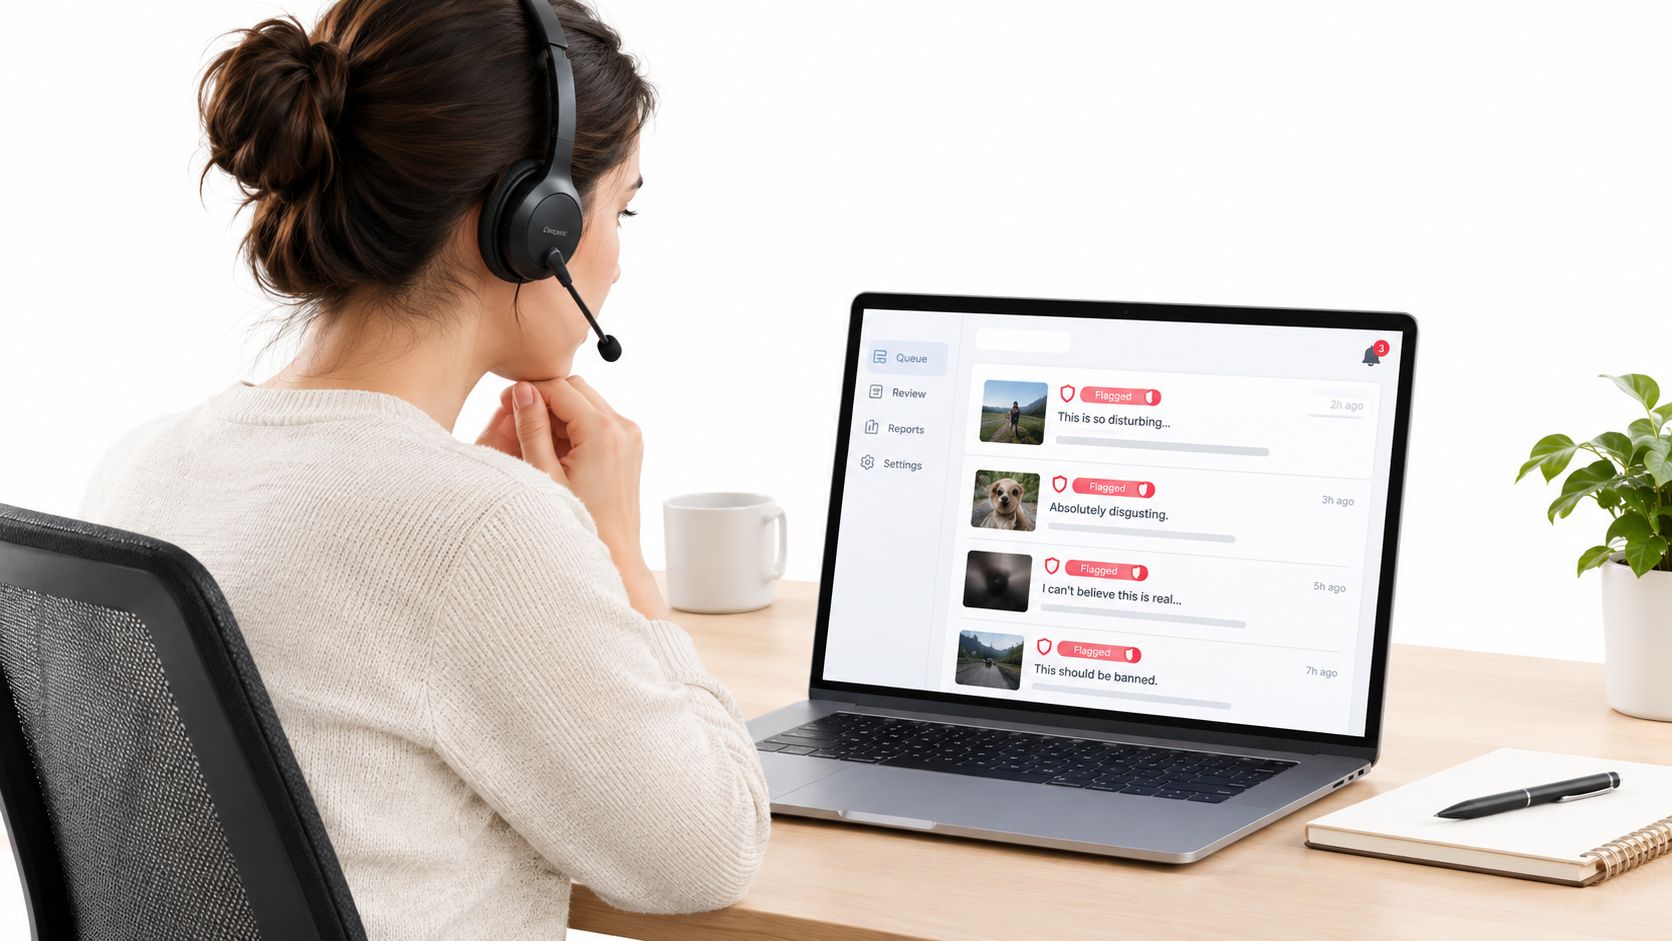
A managed trust and safety team handles text, images, video or live streams against your documented rules.
Moderators decide what stays, what is removed, what receives a warning, what triggers account action and what requires legal or policy escalation. Your internal team still owns the policy, enforcement philosophy and high-impact decisions.
Start with low-risk queues such as spam, duplicate posts or obvious scams. Do not hand over permanent bans or legally sensitive cases until reviewers show consistent judgment. TikTok's first-half 2025 EU transparency report shows the scale these operations can reach, reporting around 27.8 million removed pieces of violating content and a 99.2% moderation accuracy rate in its official report. The operating challenge is queue routing, review sampling and escalation design, not just adding more moderators.
Write 20 to 30 policy examples across severity levels. Assign an internal policy owner who answers clarification requests, then audit 5 to 10% of moderated content weekly during the first month. Track accuracy, appeal outcomes, queue age and escalation reasons.
Modern moderation is also more specialized than generic volume handling. PwC describes the shift as “from scale to specialization”, which is a good warning against one universal queue.
BUNCH supports online community moderation for user-generated content and community channels. Outsourcing is not the right answer if your policy is politically or culturally unresolved, since external reviewers cannot repair an unclear standard.
3. Customer Support and User Experience Operations
Support is often the first workflow a growing product team underestimates. The backlog then becomes a product problem, a retention problem and a morale problem.
A managed support team can handle password resets, billing changes, account issues, API documentation questions, order status, returns or basic troubleshooting through email, chat, phone and ticketing systems. Agents follow your runbook and escalation rules. Your product and engineering teams own defects, roadmap decisions, refunds outside policy and sensitive account actions.
Begin with email if the product is complex. It gives new agents room to research and document answers. Add live chat when the knowledge base and escalation paths are stable. A runbook should contain 50 to 100 scripted responses and decision trees for common issues, but agents also need permission to flag gaps instead of forcing every case into a script.
Track first response time, resolution rate and escalation rate weekly. A rising escalation rate usually points to missing documentation, product confusion or training gaps. Kforce's managed services case study set a target of a 98% calls-answered rate with less than 30 seconds of hold time, illustrating how a support operation can be defined through access and wait-time commitments rather than a vague promise to improve service in its case study.
The provider can own the queue. It cannot own a product decision your company has not made.
Hold a monthly review with the support lead and examine recurring contacts, not only dashboard totals. A managed team is valuable partly because it gives you a steady stream of product defects and confusing flows customers already found.
4. AI Safety, Model Evaluation and Red Teaming
Model evaluation is not the same as checking whether an answer sounds plausible. Evaluators need a rubric for safety, factuality, relevance, bias and context-dependent harm.
A managed AI safety team can rate model outputs, test adversarial prompts, identify jailbreaks, compare responses against ranked preferences and label reinforcement learning data. Your ML or safety team owns the evaluation design, release gate and response to severe findings. The external team owns repeatable test execution and structured evidence.
For an LLM, start with 10 to 20 examples showing good, mediocre and bad outputs. Include ambiguous cases. Evaluators should flag uncertainty rather than inventing a confident label. Track inter-rater agreement on a weekly sample, then investigate disagreement by category. Low agreement usually means the rubric needs work or the team lacks domain context.
Red teaming should begin with a small internal exercise. Your team can identify the model's threat surface, while external evaluators broaden the prompt set and run repeatable tests across versions. Rotate evaluators periodically to reduce fatigue and expose blind spots.
A practical governance process should connect findings to owners. A guide to building an AI governance program can help frame that responsibility, but no framework replaces a release decision inside your company.
Outsource this work when you have stable evaluation criteria and enough test volume to justify a dedicated queue. Keep it internal when the model affects safety-critical decisions and your organization has no expert available to adjudicate difficult cases.
5. Know Your Customer Verification and Identity Validation
KYC fails when reviewers must make policy decisions without clear evidence or escalation rules.
The managed team handles intake, document review, evidence capture and routing. Reviewers compare government-issued IDs, selfies, address evidence and risk signals with your documented requirements. They approve, reject, request more information or escalate a case. Your legal and compliance team owns the rules, jurisdictional interpretation and final accountability.
Start with a low-risk cohort, such as users in one jurisdiction. Add complex document types and cross-border cases only after the queue is stable. Define what counts as an unreadable document, possible mismatch, sanctions concern or suspected fraud pattern. Every rejection needs a reason code and an appeal path.
Automated checks can validate contact data before a case reaches a reviewer. An Email Validation API can handle format and deliverability checks, leaving reviewers to examine documents and resolve identity mismatches. Set the handoff rules in advance. For example, a name mismatch between an ID and selfie should escalate to compliance with the evidence, reason code and reviewer notes attached.
Track approval rate, decision time, appeal rate and manual escalation reasons. A falling approval rate may reflect stricter review, a different applicant mix or a training problem. Each cause requires a different response, so review samples rather than optimizing one metric.
We also support KYC and identity verification workflows for fintech, crypto and prediction market companies at BUNCH. An external team is the wrong fit if your compliance function cannot review exceptions or if you expect the provider to interpret unresolved legal requirements.
6. Community Management and User Engagement Operations
Community management sits between support, moderation and product marketing. That overlap is why ownership gets messy.
A managed community team welcomes members, answers recurring questions, facilitates discussions, enforces conduct rules and routes feature requests or complaints. Your internal community lead owns tone, major announcements, partnerships and decisions that affect the relationship with users.
Give managers a charter with values, prohibited behavior, escalation rules and examples of the desired tone. Assign one internal liaison who can approve announcements and answer policy questions. Without that person, community managers either wait too long or make decisions they should not own.
For a SaaS forum, the queue may include feature requests, bug reports and onboarding questions. For a crypto community, it may include Telegram or Discord questions about launches, impersonation and account safety. The work needs cultural fluency, not just response speed.
Track new members, active participation, sentiment shifts and escalations as directional signals. Do not turn community health into a single target. A team can increase activity while making conversations less useful.
Community managers should be close enough to users to hear problems early, but not so independent that they create unofficial product policy.
Outsource daily engagement when volume is repeatable and your internal team can define the voice. Keep strategic relationship-building in-house when the community is the product or founders are still shaping its identity.
7. Data Entry, Validation and Dataset Maintenance
Data maintenance is unglamorous until a broken customer record reaches underwriting or a flawed training label changes a model.
A managed team can enter information from forms or PDFs, verify records against source documents, deduplicate entries and correct inconsistent fields. Your data team owns the schema, field definitions and validation rules. The external team owns batch processing, exception logging and first-line correction.
Start with a data dictionary containing field definitions and 10 to 20 example records. Build a checklist for every batch, then audit the first 100 to 200 records yourself. That early review usually exposes unclear rules before they spread across the dataset.
Automated checks should catch missing fields, invalid formats and duplicate identifiers. Operators should spend their time on judgment calls, such as whether two similar customer records represent the same person or whether a source document contains a genuine exception.
A useful operating design separates production from validation. One person enters the record, another checks critical fields and a supervisor reviews recurring disagreement patterns. The exact mix depends on risk, data type and source quality.
This service fits teams with stable schemas and ongoing volume. It does not fit a company still deciding what each field means. Outsourcing an unstable schema only hides design problems behind a larger queue.
8. Human-in-the-Loop AI Validation and Model Monitoring
A model can pass pre-launch tests and still fail when real users introduce new data, edge cases or distribution shifts.
Human validators review selected production outputs, classify errors and escalate patterns to the ML team. For a lending model, they may inspect high-risk approvals. For a recommendation engine, they may assess relevance. For a moderation system, they may review borderline decisions before automatic removal. Your ML team owns thresholds, retraining and release decisions. The managed team owns sampling, review consistency and evidence capture.
Start with the highest-risk predictions, not every output. Define acceptance criteria before launch, then track validation accuracy, agreement between reviewers and error categories. Corrections should feed a retraining dataset or a documented model change process.
A weekly review with ML, product and operations keeps the queue connected to model improvement. If validators repeatedly flag the same error, changing the reviewer script will not solve it. The model, input data or decision threshold may need attention.
The main trade-off is coverage versus cost. Broad sampling finds more weak signals, while risk-based sampling gives faster attention to consequential cases. Outsourcing works when your team can define the sampling logic and act on escalations. It fails when validators become a reporting layer no one uses.
Managed Services, 8-Point Comparison
Choose the Workflow, Not Just the Vendor
A good managed service has four properties: repeatable volume, clear policy ownership, measurable quality and an escalation path for exceptions. It also requires acceptable data access, documented handoffs and an internal owner who can make decisions when the playbook stops being clear.
The provider should own the operational queue, staffing, training, quality review and reporting. Your company should retain product strategy, policy, compliance accountability, model release decisions and high-risk judgment. That split prevents the most common failure mode, outsourcing responsibility without outsourcing the work required to deliver it.
The managed services market's scale helps explain why this model appears across cloud operations, security, support and specialized workflows. Grand View Research values the global market at USD 401.2 billion in 2025 and projects USD 847.4 billion by 2033, with North America holding a 33.0% share in 2025 in its market analysis. For an operations lead, the useful implication is not that every workflow belongs outside the company. It is that recurring delivery models are now established enough to evaluate on operating design.
That distinction should shape your procurement brief. Ask who owns exceptions, how quality is sampled, which decisions remain internal and what happens when volume changes.
When do managed services fit a technology company?
They fit when the workflow repeats, volume is difficult to staff internally and quality can be measured. They do not fit when policy is unresolved or every case requires a founder, product leader or legal expert.
What should remain in-house?
Keep product direction, policy ownership, regulatory accountability, model release decisions and high-risk escalations internal. A provider can execute a rule, but your company remains accountable for the rule.
How should a pilot be structured?
Choose one queue, define the input and output, document edge cases, agree on quality review and set an escalation path before work begins. Start with a limited batch or lower-risk category, review disagreements with the provider and expand only after the operating rules are stable.
Here at BUNCH, we build managed human-in-the-loop teams for data operations, data labeling, content moderation, customer support, community operations, KYC and AI validation. Got a defined workflow with real volume, and a quality or hiring problem you can't solve in-house? Talk to us. Book a call with a BUNCH expert to walk you through the scope, the handoffs and how we'd review the work.
About the Author